
Lesson 14 · Advanced · 15 min
Long context: process one million tokens in a single pass
Harness Gemini's massive context window: process 500-page dossiers in one pass and locate isolated facts without fragmented chunking.
- Goal
- You will ingest and query massive corpora spanning hundreds of pages in one pass to generate comprehensive, unfragmented executive syntheses.
- Skills
- Frame

Your first attempt, unaided
Upload several lengthy PDF files into Gemini and prompt it to conduct a cross-document audit identifying contradictions without chunking.
Gemini's one-to-two-million token context window ingests entire enterprise document libraries without preliminary chunking or loss of nuance. To harness this massive capacity effectively, anchor critical guidance at both ends of the prompt and require exact page citations to neutralize attention drift across long texts.
1The death of chunking: holistic comprehension of massive files
The death of chunking allows teams to achieve holistic comprehension of massive files within a single analysis session. Gemini removes the artificial boundaries imposed by traditional retrieval-augmented architectures by retaining all source materials in active memory.
A one-million token context window accommodates roughly 750,000 words, equivalent to dozens of audit reports, regulatory binders, or complete software repositories. The model seamlessly correlates a footnote in volume one with a technical appendix in volume three without semantic loss. To prevent attention degradation across long documents (lost in the middle), structure your prompt by positioning primary constraints at the start and conclusion of the query.
Document analysis approach Traditional RAG architecture Native Gemini long context Operational advantage Source ingestion Chunked into disconnected fragments Ingests entire corpus in one piece Preserves distant causal dependencies Cross-volume synthesis Inconsistent across wide horizons Exhaustive across all sections Uncovers subtle cross-document contradictions Document setup Complex vector database indexing Direct upload of original PDF files Instant deployment without custom pipelines 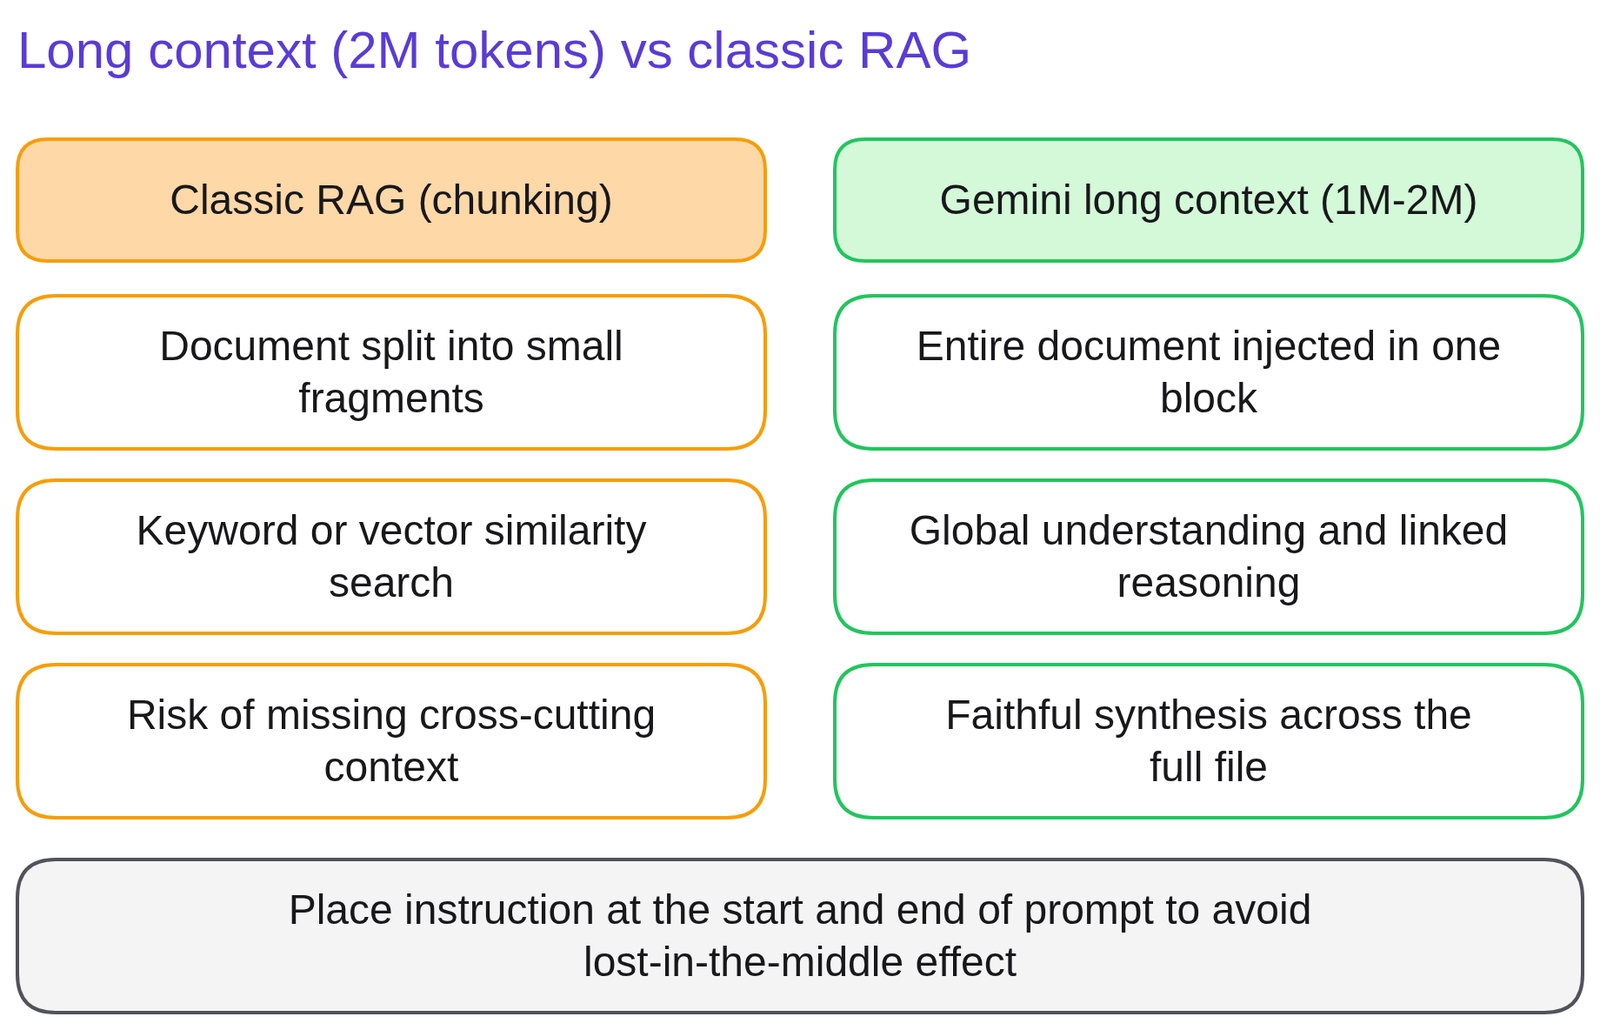
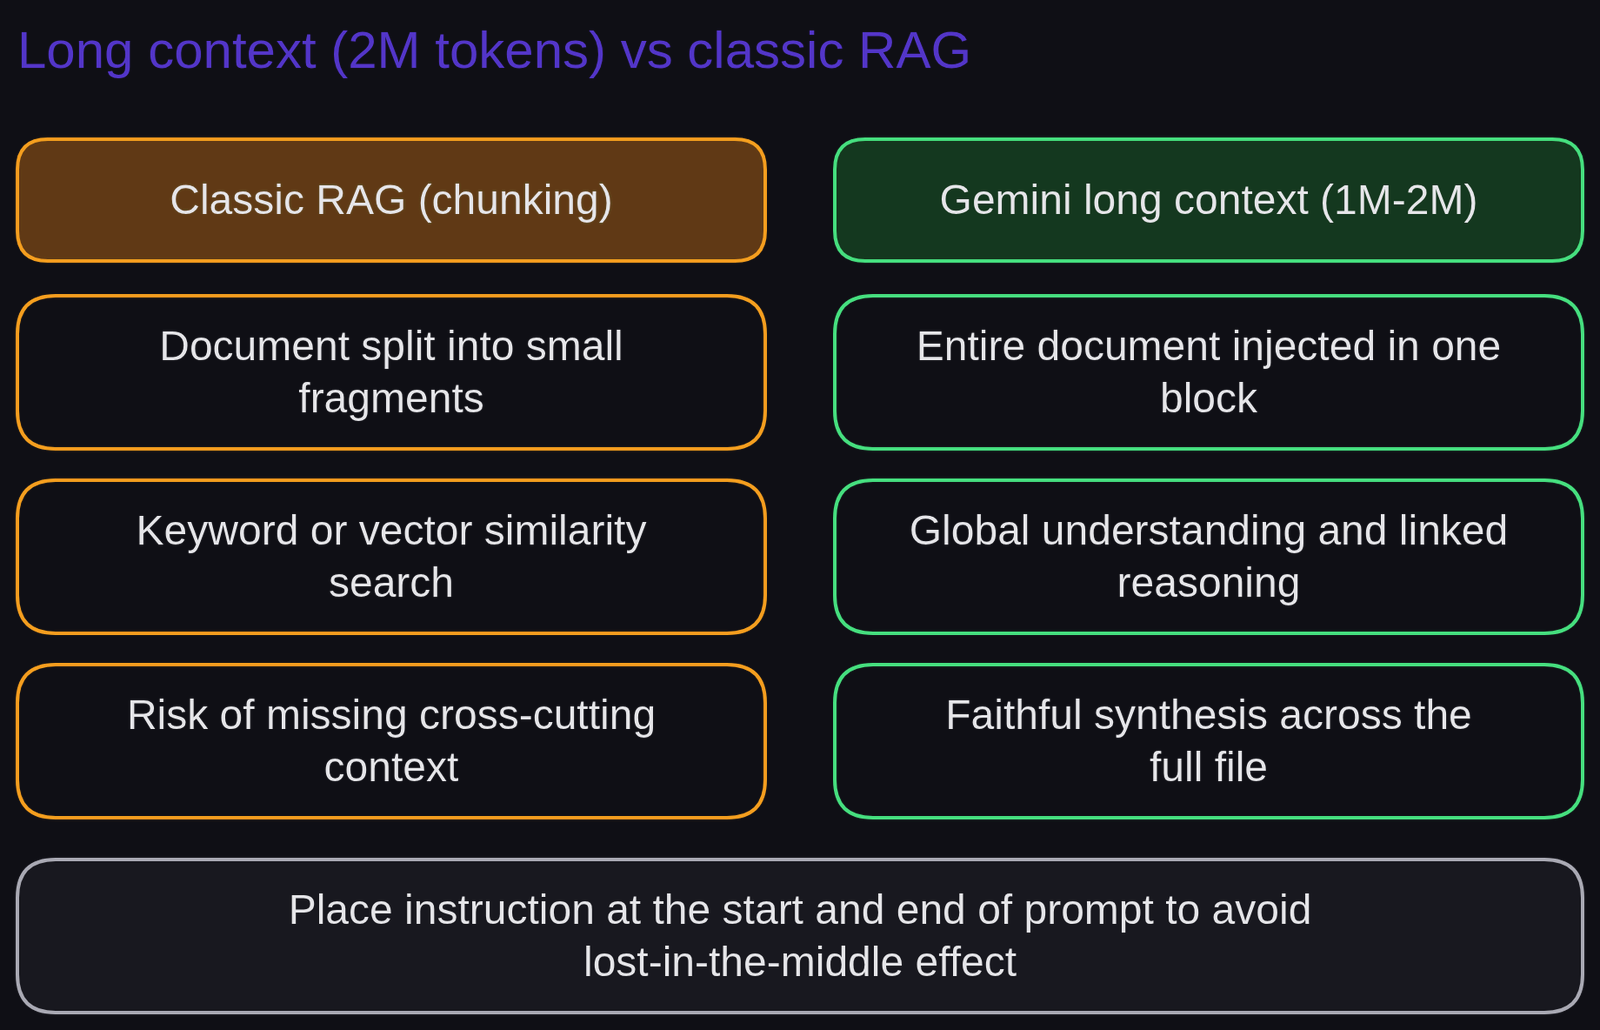
Diagram 'Long context vs traditional RAG'Diagram generated by AI and reviewed 2Cross-examining three distinct 150-page financial audit reports
Cross-examining three distinct 150-page financial audit reports demonstrates how Gemini massive context window identifies accounting discrepancies that escape fragmented manual reviews.
An internal audit director needs to compare asset depreciation schedules across three newly acquired European operating subsidiaries.
Weak prompt.
Here are three attached financial audit reports. Tell me if there are any differences between the subsidiaries.Gemini skims the documents, outputting a superficial summary of general business operations without highlighting specific accounting discrepancies.
Strong prompt.
Based on the three attached audit reports (Subsidiaries A, B, and C), construct a comparative table of depreciation timelines applied to fixed assets. Expected columns: Asset Category, Subsidiary A Schedule, Subsidiary B Schedule, Subsidiary C Schedule, and Identified Accounting Variance. Include exact source page citations in every cell. 130 words.The difference. The prompt confines the inquiry to specific accounting schedules and demands page-level citations, compelling the model to examine the full 450 pages with rigorous precision.
3Locating a documentary needle within a massive information haystack
Locating a documentary needle within a massive information haystack trains you to verify Gemini perfect recall across large corpora by posing an intricate inquiry requiring complete source comprehension.
Upload a document bundle exceeding 200 pages (annual disclosures, technical manuals). Ask a question regarding an obscure contractual carve-out or technical exception buried deep in the appendices.
Run this prompt:
'Across the attached document set, locate the clause governing delay penalties during adverse weather conditions. Identify the specific document, the exact article number, and quote the 25-word provision verbatim.'
Self-evaluation rubric: (a) the exact source document is identified within the corpus ; (b) the page and section reference points to genuine text ; (c) the quotation is transcribed verbatim without extrapolation.
4Loosening prompt discipline assuming the model automatically knows what matters
Loosening prompt discipline assuming the model automatically knows what matters produces superficial outputs, as massive context without targeted boundaries dilutes analytical focus.
The larger the uploaded corpus, the more surgical your prompt constraints must be. Requesting a 'general summary' of a thousand-page dossier causes Gemini to return generic platitudes while missing subtle risks buried inside technical appendices.
Fix: frame targeted inquiries specifying exact operational perspectives, entities to cross-examine, and expected table schemas.
Rule to remember: massive source volumes demand heightened prompt precision to avoid semantic drowning.
5Quiz
Three questions, instant feedback. Each option comes with an explanation.
6Proof of mastery
Ingest a collection of documents exceeding 100 pages combined into Gemini and generate a cross-comparative brief citing page numbers from at least two sources.

Criteria
What you wrote at the start of the lesson


Going further
Examine glossary entries for context window, RAG, and in-context learning. The next lesson, Analyze a video with Gemini, applies long context across temporal multimedia. To build persistent organizational repositories, explore Create a custom Gem.
Frequently asked questions
What does one million tokens represent in practical terms?
One million tokens equals roughly 750,000 words, representing around 1,500 pages of text, one continuous hour of raw video, or over 30 hours of audio recordings.
What is the 'Needle in a Haystack' benchmark?
It is an evaluation measuring whether a model can retrieve an isolated factual needle planted anywhere within a massive corpus. Gemini achieves recall accuracy exceeding 99% across its window.
Does long context render RAG obsolete?
For focused dossiers spanning hundreds of pages, long context beats naive RAG pipelines. For enterprise knowledge repositories indexing millions of files, vector retrieval remains necessary for initial filtering.